Function Frenzy
Objectives
Get more comfortable using recursion
Learn how to document functions with docstrings
Learn how to add basic tests to your code with
assertstatements
Background
We’ve seen previously how functions let us reuse code and why reusing code is important. Now, it’s time to exercise our ability to use recursion to solve programming problems. Recursion is a very powerful technique that takes advantage of a problem’s ability to be broken down into smaller but similar sub-problems and allows us to reuse code very efficiently and concisely.
Thinking about problems in a recursive way can be very difficult and takes time to get used to. That’s okay! Don’t be afraid to ask for help or sketch out your ideas on paper/whiteboard before diving in and writing code.
Getting Started
Create a new file, we will call ours frenzy.py, for example, using vscode or touch.
Here is a little bit of code to paste, if you’d like to use it to get started:
# Vassar CS Camp
# Name: [your name here]
# Filename: frenzy.py

def leng(s):
    """leng returns the length of s
       Argument: s, a string or list
    """
    if s == '' or s == []: # if empty string or empty list
        return 0
    else:
return 1 + leng(s[1:])For these exercises, the mult, dot, ind, scrabbleScore, and transcribe
functions should all be done using recursion.
Visualize Recursion
Some people have used this online Python visualizer to build intuition about how recursion works. A couple of details: to visualize a recursive call, you’ll need to do the following.
- Define your recursive function
- Call it
You can start out by copying the starter code above into the visualizer and adding below it:
leng('four') # returns 4Hit the ‘Visualize Execution’ button followed by a few presses of the ‘Forward
’ button to watch it execute step-by-step. If the Python visualizer isn’t your thing, that’s okay! If you like it, great! Make a bookmark!
Use Docstrings
Also, for each function be sure to include a docstring that indicates what the function’s arguments mean and what its return value means, i.e., what the function “does.” You can think of a docstring as just a special comment. It won’t affect your code at all but is good practice to include.
Here’s an example of a docstring that you are welcome to use for mult and as a
template for the others:
def mult(n, m):
    """mult returns the product of its two arguments
       Arguments: n and m are both integers
       Return: the result of multiplying n and m
    """

# code here ...The docstring needs to be indented to the same level as body of the function it’s in. Python is picky about this.
Always Test
Be sure to test your functions! It’s tempting to write a function and feel like it works, but if it hasn’t been tested, it may have a small (or big!) error that causes it to fail.
For these first few exercises, we provide a set of tests that you can (and should!) paste into your code. Then, when you run your file, the tests will run and you can check (by sight, in this case) whether any of the tests have not passed.
If a test fails, you will get an AssertionError and the test case that caused
the error will be provided in the error message.
Here’s an example using the flipside(s) function from a previous exercise.
Paste this into your file and run it:
def flipside(s):
  """flipside swaps s's sides
     Argument s: a string
  """
  x = len(s)//2
  return s[x:] + s[:x]

# tests
assert flipside('carpets')  == 'petscar'
assert flipside('homework') == 'workhome'
assert flipside('flipside') == 'sideflip'
assert flipside('az')       == 'za'
assert flipside('a')        == 'a'
assert flipside('')         == ''
When you run this, you should get silence from the tests. Try adding a malicious test case to force an error:
assert flipside('') == 'verywrong'When you run your file now, you should get an error that looks something like this:
Remember to remove the always-failing test case or your file will always fail to run!
For all the functions below, be sure to paste in the tests, too—and run them!
The Exercise
Problem 1 Write the function
mult(n, m).Here is a description:
mult(n, m)should return the product of the two integersnandm. Since this would be a bit too easy if the multiplication operator (*) were used, for this function, you are limited to using the addition, subtraction, and negation operators, along with recursion.
If you run in to problems with negative numbers, just move on and come back later! Consider negative numbers a bonus challenge.
Here is some example output:
Here are some tests:
If you are implementing
mult(n, m)for negative numbers as well, here are some more tests:
Problem 2 Write the function
dot(L, K).Here is a description:
dot(L, K)should return the dot product of the listsLandK. If the two argument lists are not of equal length,dotshould return0.0. If the two lists are both empty,dotalso should return0.0. You should assume that the argument lists contain only numeric values.
What’s the dot product?
The dot product of two lists is the sum of the
products of elements that are in the same position in their containing lists.
In the first example, the output is computed via the expression 5*6 + 3*4.
Note that 5 and 6 are both the first element of their lists and 3 and
4 are both the second element of their list. Each pair is multiplied
together and the resulting values are summed to yield 42.0.
Here is some example output:
Here are some tests:
assert dot([5, 3], [6, 4])                       == 42.0
assert dot([1, 2, 3, 4], [10, 100, 1000, 10000]) == 43210.0
assert dot([5, 3], [6])                          == 0.0
assert dot([], [6])                              == 0.0
assert dot([], [])                               == 0.0
Problem 3 Write the function
ind(e, L).Here is a description:
ind(e, L)takes in a sequence (list or string)Land an elemente. Your functionindshould return the index at whicheis first found inL. The index begins at0, as is usual with lists. Ifeis not an element ofL, thenind(e, L)should return the integer equal to len(L). You may not use the built-inindexfunction.Here is some example output:
Here are some tests:
assert ind(42, [55, 77, 42, 12, 42, 100]) == 2
assert ind(42, list(range(0, 100)))       == 42
assert ind('hi', ['hello', 42, True])     == 3
assert ind('hi', ['well', 'hi', 'there']) == 1
assert ind('i', 'team')                   == 4
assert ind(' ', 'outer exploration') == 5In the last test and example, the first argument to ind is a string of a
single space character, not the empty string.
Problem 4 Write the function
letter_score(let).Here is a description:
letter_score(let)should take a single argument, which is a single-character string, and return the value of that character as a Scrabble tile. If the argument is not one of the letters from'a'to'z', the function should return0.To write this function you will need to use this mapping of letters to scores:
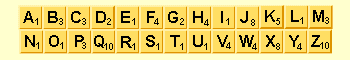
What!? Do I have to write 25 or 26
if/elif/elsestatements? No! Instead, use theinkeyword:
Ok… but how does this help…?
Consider a conditional such as this:
if let in 'qz':
return 10letter_score does not require recursion. But recursion is used in the next
one…
Here is some example output:
For this problem, try writing some test cases yourself. Try and break your function with weird input!
TipMake sure to test
letter_scoreindependently before you go on toscrabble_score. If you don’t, how will you know whether a testscrabble_scorefailed is because ofletter_scoreorscrabble_score?Problem 5 Write the function
scrabble_score(S).Here is a description:
scrabble_score(S)should take a string argumentS, which will have only lowercase letters, and should return the Scrabble score of that string. Ignore the fact that, in reality, the availability of each letter tile is limited.
Use the above letter_score function and recursion.
Here is some example output:
Here are some tests:
assert scrabbleScore('quetzal')                    == 25
assert scrabbleScore('jonquil')                    == 23
assert scrabbleScore('syzygy')                     == 25
assert scrabbleScore('abcdefghijklmnopqrstuvwxyz') == 87
assert scrabbleScore('?!@#$%^\*()')                == 0
assert scrabbleScore('')                           == 0
Problem 6 Write the function
transcribe(S).Here is a description:
In an incredible molecular feat called transcription, your cells create molecules of messenger RNA that mirror the sequence of nucleotides in your DNA. The RNA is then used to create proteins that do the work of the cell.
transcribe(S)should take an argument that is a stringS, which will have DNA nucleotides (A,C,G, andT).There may be other characters in
S, too, though they should be ignored by your transcribe function by simply disappearing from the return value. These might be spaces or other characters that are not really DNA nucleotides.
transcribeshould return the messenger RNA that would be produced from that stringS. The correct return value simply uses replacement:
As becomeUsCs becomeGsGs becomeCsTs becomeAsAny other input characters should disappear from the result altogether.
As with the previous problem, you will want a helper function that converts one nucleotide. Feel free to use this as a start for this helper function:
def one_dna_to_rna(c):
    """Converts a single character c from DNA
       nucleotide to complementary RNA nucleotide """

    if c == 'A':
        return 'U'

    # etc, etc...
Here is some sample output:
Here are some tests:
assert transcribe('ACGTTGCA') == 'UGCAACGU'
assert transcribe('ACG TGCA') == 'UGCACGU' # Note that the space disappears
assert transcribe('GATTACA')  == 'CUAAUGU'
assert transcribe('cs5')      == ''        # Note that the other characters disappear
assert transcribe('')         == ''
Bonus Exercise
Problem 1 Write two functions that translate from English to Pig Latin.
Be sure to test and provide docstrings for your functions!
Piglet Latin Write the
piglet_latin(s)function, which accepts an argument that is a strings.swill be a single word consisting of lowercase letters. Then,piglet_latinshould return the translation ofsto “Piglet Latin”, which has these rules:
If the argument has no letters at all (the empty string), your function should return the empty string
If the argument begins with a vowel, the Piglet Latin result simply appends the string
'way'at the end.'y'will be considered a consonant, and not a vowel, for this problem. Example:piglet_latin('one')returns'oneway'If the argument begins with a consonant, the Piglet Latin result is identical to the argument, except that the argument’s initial consonant is at the end of the word instead of the beginning and it’s followed by the string
'ay'. For example,piglet_latin('be')returns'ebay'.Of course, this is not full Pig Latin, because it does not handle words beginning with multiple consonants correctly. For example,
piglet_latin('string')returns'tringsay'when it should return'ingstray'.You’ll fix this next!
Pig
letLatin Write thepig_latin(s)function that handles the rules above and handles more than one initial consonant correctly in the translation to Pig Latin. That is,pig_latinmoves all of the initial consonants to the end of the word before adding'ay'. (You may want to write and use a helper function to do this—see the hint below.)Also,
pig_latinshould handle an initial'y'either as a consonant OR as a vowel, depending on whether the y is followed by a vowel or consonant, respectively. For example,'yes'has an initial y acting as a consonant. The word'yttrium', however, has an initial y acting as a vowel.Here is some example output:
>>> pigLatin('string')
ingstray

>>> pigLatin('yttrium')
yttriumway

>>> pigLatin('yoohoo')
oohooyay
Tests? These we’re leaving up to you!
One way to use recursion to assist in this is to write an initial_constants(s)
function that returns a string of all the initial constants in its string
argument. Thus, if s starts with a vowel, the empty string '' will be
returned or if s starts with some sequence of consonants, you’ll have them
separated in their own string.
If you think about this problem thoroughly, you’ll find that not every possible case has been accounted for—you are free to decide the appropriate course of action for those “corner cases.” But, remember to document the behavior that you implement!
Oodgay ucklay!